Anthropic measures its own pace: Claude leads 26% of R&D
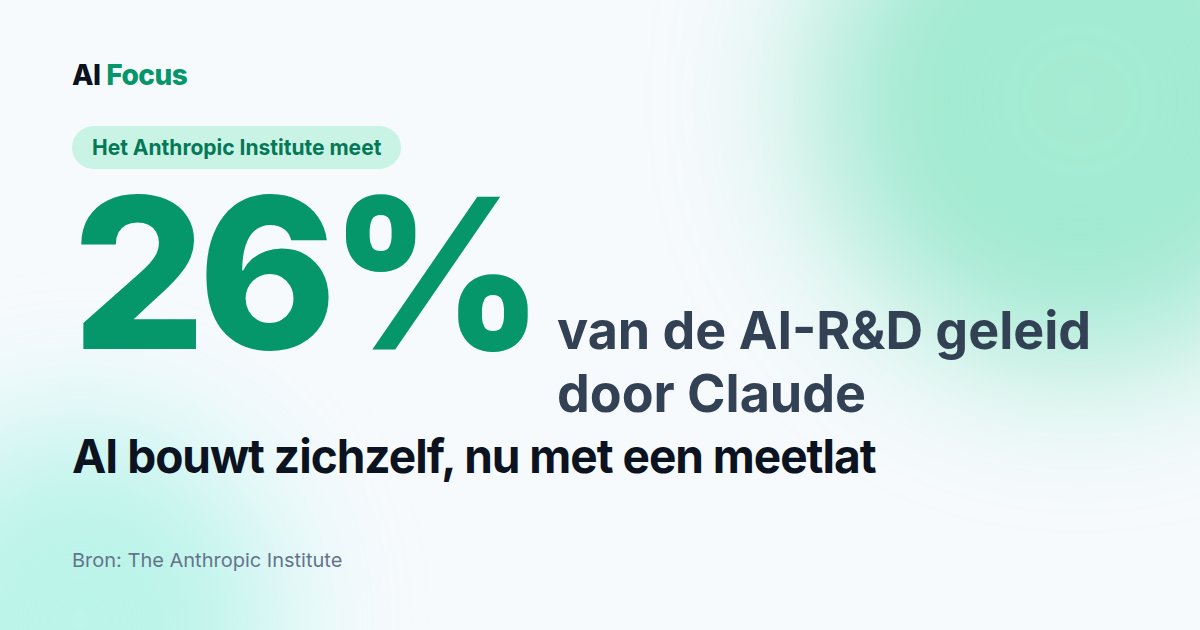
How much of the work on the next Claude is being done by Claude itself today? Anthropic now puts a number on that: 26%. It appears in “Measurements for understanding the pace of AI development inside frontier labs”, a publication from The Anthropic Institute, the research institute Anthropic launched in March 2026, dated September 17, 2026 on the company’s newsroom. The piece bundles three measurements intended to give outsiders, from the general public to third parties and governments, insight into the pace of AI development inside a frontier lab. The motivation is stated plainly: “as the world considers slowing the pace of frontier AI development”, now that the world is weighing whether to slow the pace of frontier AI. After a week where that slowdown debate was mostly words, here is something you can count. OpenAI already showed early acceleration data earlier this month; what is new is that a lab proposes its figures as a repeatable measurement standard, something with which you could actually verify such a slowdown.
Three measurements from the engine room
The measurements themselves come from July and August 2026. The first, and immediately the most striking, measures how much AI research is done by AI. Anthropic uses an “Automation Level” scale from AL0 to AL5 for this: at AL3, AI collaborates; at AL4, it leads the work; at AL5, everything would run fully autonomously. The result for August 2026: Claude leads 26% of Anthropic’s AI research and development work, and more than 90% of that work sits at or above the level where AI collaborates. Nothing runs fully autonomously. Anthropic cast that exercise into a prototype with a name that leaves little to the imagination: the Anthropic R&D Automation Index.
| Measurement | What it shows | Figure |
|---|---|---|
| AI-led AI research | What share of its own AI R&D work Claude leads (AL4 on the AL0-AL5 scale) | 26% led by Claude; over 90% at least “AI collaborates”; 0% fully autonomous |
| Agent monitoring | What share of agent actions passes through a monitor before execution | 100%, with about 30,000 simultaneous agents; 0.002% blocked (approximately 1 in 47,000) |
| Compute for safety | What share of R&D compute goes to safety research | About 6% (week of July 13-20, 2026); within the AI-driven portion about 12% |
The second measurement addresses oversight. On Anthropic’s most-used internal platform, about 30,000 agents run simultaneously at any given time, AI systems that independently perform research and programming work. Every single one of their actions, 100% of them, passes through an online monitor before it is executed. That monitor blocked 0.002% of actions, about 1 in 47,000. In addition, offline monitors review transcripts after the fact; they flag 1 to 2 transcripts per thousand for further review.
The third measurement counts compute. In the week of July 13-20, 2026, about 6% of compute for AI R&D went to safety research. If you look only at the AI-driven portion of that R&D work, the share climbs to about 12%.
Exactly the instrument Brussels was asking for
The timing is striking. This month, Anthropic CEO Dario Amodei called for a slowdown, joined by Sam Altman and Elon Musk, and dismissed by Donald Trump as a “hoax”. And barely a day before this publication, Ursula von der Leyen delivered her State of the Union, in which she warned of self-improving models and wanted to cooperate with Canada and the UK on “model evaluation, verification, early warning”. Read von der Leyen’s call for model evaluation and verification again: what Anthropic publishes here is exactly the instrument she was asking for. And her concern about self-improving models gets a concrete number here, with an important nuance: no model that autonomously rewrites itself, but Claude leading 26% of the work on its own successors, under human oversight.
Anthropic is aware that a lab grading its own homework proves little, and therefore proposes verification. It wants to embed independent external evaluators from multiple organizations, with access “comparable to what internal risk assessment teams have”, comparable to what internal risk teams can see. Third parties could rerun the classifiers, the systems that assess and label the work, on samples. And the invitation to the rest of the sector is stated plainly: “Any frontier developer could publish these measures regularly, using a public methodology.” Why that matters, Anthropic says itself: “we would expect these numbers to shift if there were coordination on pacing the frontier”. If labs coordinated to pace the frontier, you should see these numbers change. This is, in other words, the yardstick by which a pacing agreement could someday be verified.
Notably, Anthropic is not alone in this movement this week. Today we also published our sister post on OpenAI’s six incidents: the same movement, labs volunteering accountability, each in their own way.
Our take
The slowdown debate this week consisted of words. Amodei warns, Altman and Musk chime in, Trump calls it a “hoax”, von der Leyen offers dialogue. All language, nothing you can count. This is the first yardstick that could make a slowdown verifiable: whoever claims to be taking it easier should now be able to show it in numbers. Last week, prompted by this same company’s compute contracts, we wrote: judge labs by what they sign, not by what they write. This publication adds the third piece: judge them by what they measure.
That figure of 26% is simultaneously reassuring and sobering. Reassuring, because nothing runs fully autonomously and every agent action passes through a monitor first. Sobering, because a quarter of the work on the next Claude is today being led by Claude. The self-improving models that Brussels warned about Tuesday are no longer science fiction: their precursor, AI leading the work on its own successor, now has a percentage, and it stands at a quarter.
The caveats belong in the picture. This is self-reporting: Anthropic measures itself, with a prototype, and so far is the only lab doing this. The 6 to 12% compute for safety research is a modest slice for a company that made caution its brand. And Anthropic wins reputation here, make no mistake: for this company, transparency is also marketing, especially as it reportedly eyes a public offering. Real value emerges only when other labs publish the same figures and external evaluators get to check them. That is exactly what Anthropic proposes. It is up to the rest of the sector to show whether “pace the frontier” is a measurable commitment, or just the next slogan.
Update 25 September 2026: what that AI-led research looks like outside AI itself, Anthropic showed with an enzyme system that 950 Claude agents found in 21 hours, although experts call the search routine and its function remains unknown.